Lumen
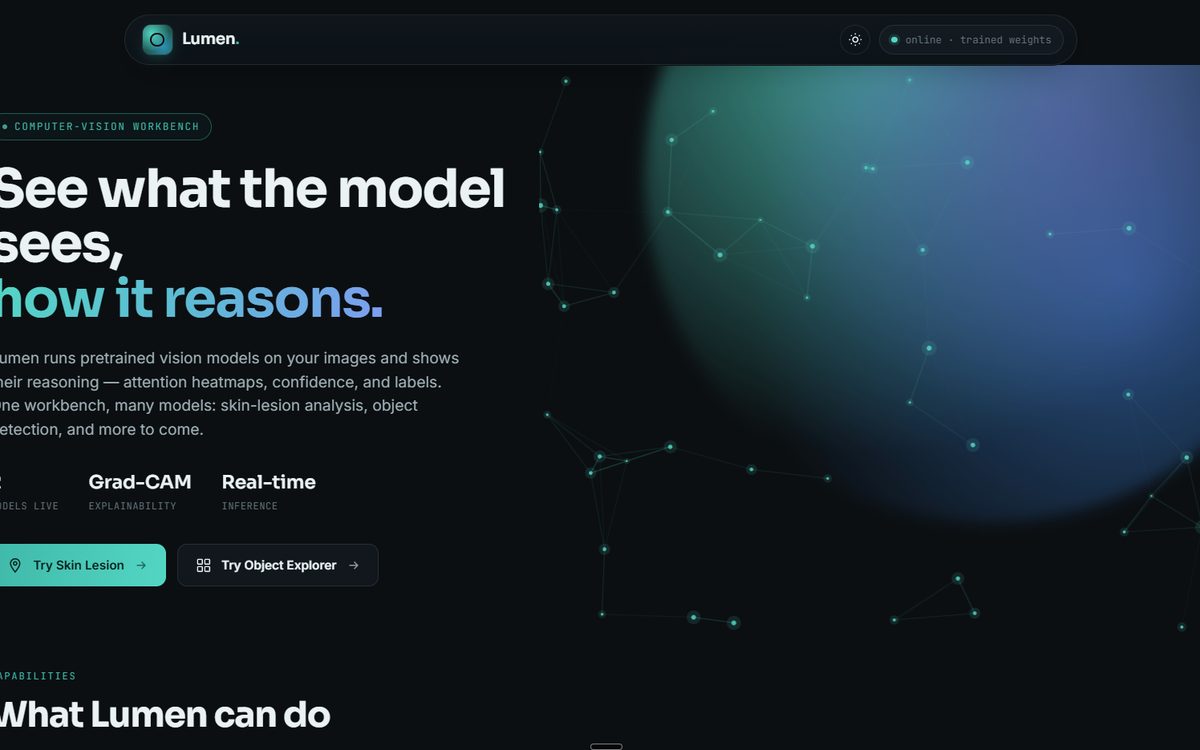
A computer-vision workbench that shows what a model sees and why — attention heatmaps, confidence, and labels, not just a verdict.
- Role
- Solo build
- Year
- 2026
- Status
- live
- Stack
- Gradio, PyTorch, ResNet-50, YOLOv8
What it is
Most vision-model demos hand back a label and nothing else. Lumen exists to show the reasoning behind it — where the model actually looked — across more than one task instead of a single-trick demo.
What I built
A shared workbench in front of pretrained models: skin-lesion analysis with a ResNet-50 and Grad-CAM heatmap over the exact region driving the call, an Object Explorer running YOLOv8 for bounding boxes and confidence, and a segmentation mode that masks every pixel by the object it belongs to. Every mode runs real-time inference in the browser off uploaded images.
What I learned
One interface, three live models, and the explainability layer (Grad-CAM attention) built in from the start rather than bolted on — proof the reasoning can be shown, not just the result.